
Quick Takeaways
- An AI detector is a tool that estimates the probability that a piece of text was generated by an AI model, based on statistical, stylistic, or embedded patterns rather than direct proof of authorship.
- Detection methods generally include statistical and linguistic analysis, trained classifiers, and other specialized approaches. Watermarking is different: it embeds a detectable signal during AI generation that can later be used to identify text produced by a participating system.
- A detector score is an estimate, not a verdict. Independent research has found accuracy varies considerably by tool, by type of writing, and by who wrote it, sometimes falling well below what vendors advertise.
- No current detection method is universally reliable across every writing style, language proficiency level, and AI model, which is part of why many institutions now treat detector scores as one input among several rather than standalone proof.
- Detection and evasion are effectively in an ongoing back-and-forth: as detectors improve, techniques for defeating them adapt too, and neither side has achieved a permanent advantage.
What is an AI detector, exactly?
An AI detector is a tool designed to analyze a piece of text and estimate the likelihood that it was generated, in whole or in part, by an AI language model rather than written entirely by a person. Tools like Turnitin, GPTZero, Originality.ai, Copyleaks, and Pangram fall into this category, and they’re widely used in education, publishing, hiring, and content moderation to flag writing that may have had AI involvement.
It’s worth being precise about what these tools actually do, because the framing matters. A detector doesn’t prove authorship the way a fingerprint or a signature might. It produces a probability score based on how closely a piece of text resembles patterns the tool has learned to associate with AI-generated writing. That distinction, between “this text resembles AI output” and “this text was definitely written by AI,” is at the center of most of the controversy around how these tools are used.
How AI detectors actually work
Detection approaches have evolved considerably, and most modern tools combine more than one method rather than relying on a single signal.
Statistical and stylometric analysis
One approach looks at measurable properties of the text itself.
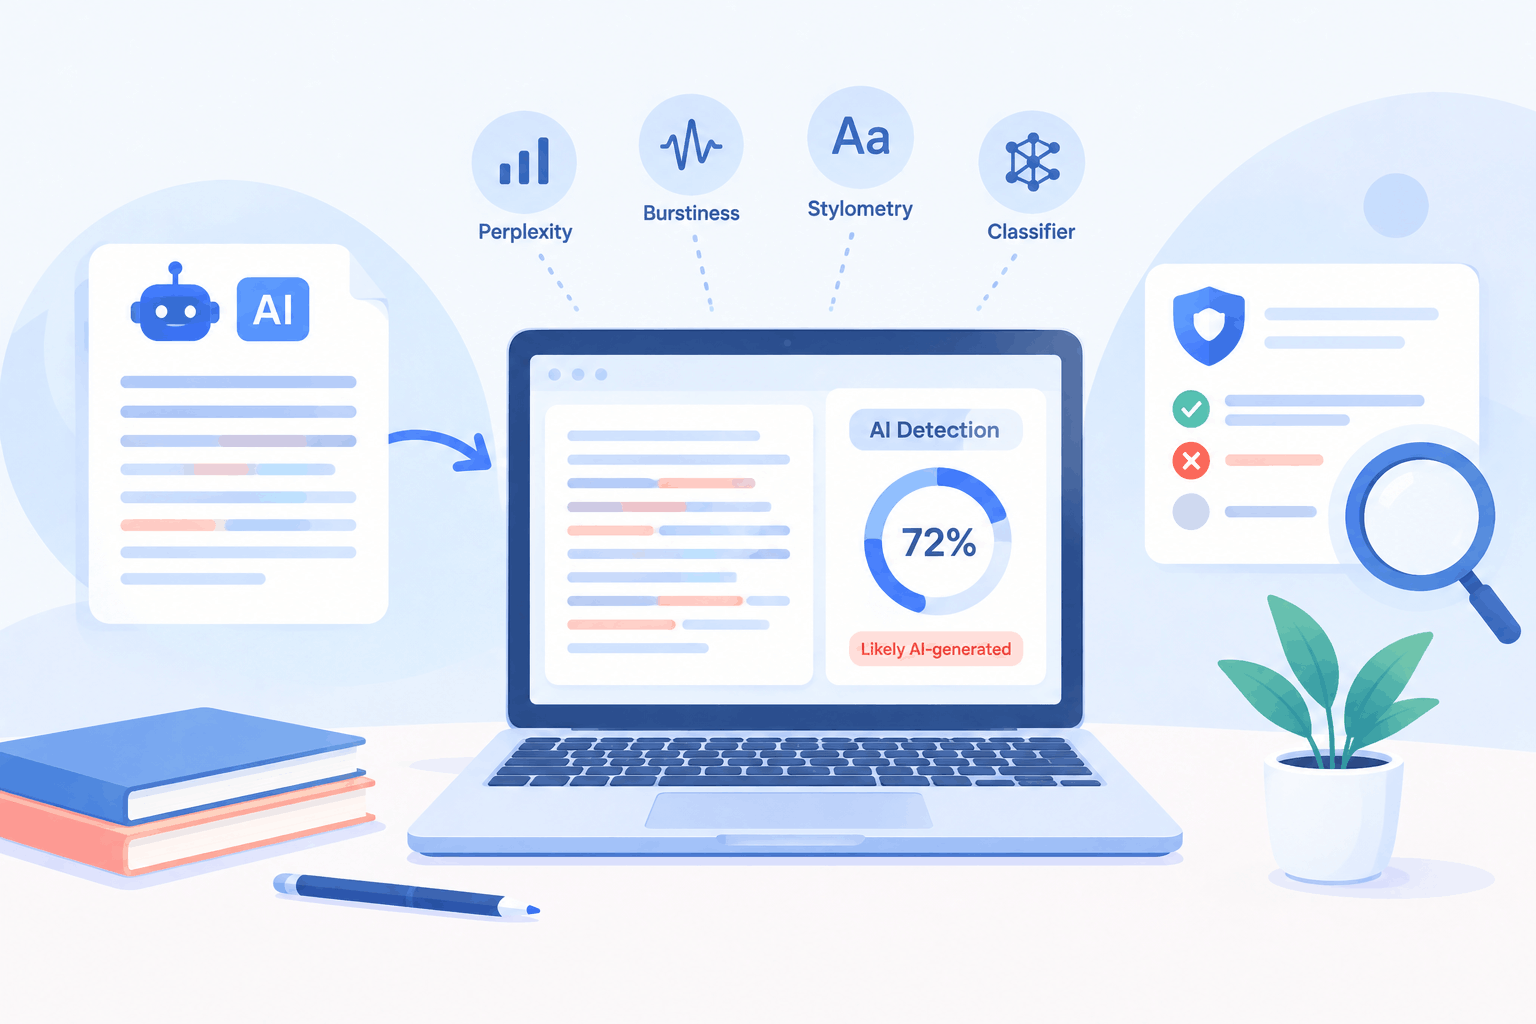
Perplexity measures how predictable a piece of text is to a language model: if a model can easily guess the next word in a sequence, perplexity is low. If the wording is unexpected or unusual, perplexity is higher. Because language models generate text by predicting likely next tokens, AI-generated text can exhibit patterns of predictability that some detection systems use as a signal. However, perplexity varies depending on the model, the text, and the language model used to measure it.
Burstiness measures how much sentence length and structure vary across a passage. Human writing can show substantial variation in sentence length and structure, while some AI-generated text may appear comparatively more uniform. However, this pattern varies by model, prompting, editing, and the type of writing being analyzed.
Stylometry goes further, examining broader stylistic fingerprints: vocabulary diversity, punctuation habits, sentence construction patterns, and other structural signals that tend to differ between human and machine writing, though not always in consistent or easily generalizable ways.
These statistical methods are attractive because they’re relatively simple, interpretable, and inexpensive to run, and they tend to perform reasonably well against older AI models or text generated with straightforward settings. They’re less reliable against newer models or text that’s been edited or paraphrased afterward.
Classifier-based detection
The more common approach in modern commercial tools involves training a machine learning classifier, often a fine-tuned transformer model, on large labeled datasets containing both human-written and AI-generated text. The classifier learns to recognize patterns across many features simultaneously, rather than relying on one or two statistical measures in isolation, and outputs a probability score based on how closely new text matches the patterns it learned during training.
This approach can be more accurate than pure statistical methods in some conditions, but it comes with a tradeoff: classifiers are only as good as the data they were trained on, and they can struggle to generalize to writing styles, languages, or newer AI models that weren’t well represented in that training data.
Watermarking
A different approach altogether involves the AI system itself embedding a hidden signal into the text as it’s generated, subtly favoring certain word choices in a consistent, trackable pattern that a person reading the text wouldn’t notice. When a detector has access to the specific watermarking scheme used, it can identify the pattern with a reasonable degree of confidence.
Watermarking is a proactive approach rather than a forensic one; it depends on the AI system’s creator having implemented it in the first place, and it has real limitations. Not all AI models use watermarking, there is no single industry standard for how it is implemented, and research has shown that editing and paraphrasing can affect the strength and detectability of some watermarking schemes.
Zero-shot and likelihood-based methods
A more specialized category, exemplified by methods like DetectGPT, doesn’t rely on a trained classifier at all. Instead, it probes how a candidate piece of text behaves under small perturbations, essentially asking whether the text sits in a region of the underlying language model’s probability landscape that’s characteristic of machine-generated content. These methods can be effective in specific research settings but are generally more computationally intensive and less commonly discussed in mainstream commercial tools than classifier-based approaches.
Why detector accuracy is more complicated than vendor marketing suggests
Detection companies frequently advertise high accuracy figures, sometimes close to 99%, but these numbers typically reflect the vendor’s own testing conditions, which may not represent how the tool performs on a broader, more diverse range of real-world writing.
Independent, peer-reviewed research has found that accuracy can vary substantially depending on the writing being evaluated. One frequently cited study tested seven commercial AI detectors against a specific set of TOEFL essays written by non-native English speakers and found that the detectors classified 61.3% of the essays as AI-generated for that particular sample, compared to a rate close to zero for essays from native English speakers in the same test. This result reflects one dataset and one set of tools under specific conditions, and doesn’t necessarily generalize to every detector or every type of writing, but it illustrates a real pattern that other studies have also found in varying degrees: detector performance is not uniform across different writers and writing styles.
A commonly proposed explanation relates to perplexity specifically. Non-native writers and English-language learners may use simpler vocabulary and more regular grammatical structures, which can resemble the same statistical pattern some detectors associate with AI-generated text, even when a human wrote every word. Similarly, technical, legal, and other formulaic writing styles can trigger elevated false-positive rates for related reasons, since predictable, standardized phrasing is a normal feature of those domains rather than evidence of AI involvement.
This kind of finding has prompted some institutions to reconsider how they rely on these tools. For example, Vanderbilt University disabled Turnitin’s AI-detection tool after evaluating its reliability and has stated that AI-detector scores should not be used as the sole basis for an academic-misconduct report. Practices vary by institution, but the example illustrates why detector results are increasingly treated as one piece of evidence rather than definitive proof of AI authorship.
The ongoing back-and-forth between detection and evasion
Detection and the techniques used to defeat it exist in a genuine, ongoing cycle rather than a settled contest. Academic research has repeatedly demonstrated that even fairly simple paraphrasing can substantially reduce detection accuracy across a range of detector types, including watermarking schemes, trained classifiers, and zero-shot methods. As detectors incorporate new signals to catch these evasion techniques, new evasion methods tend to emerge in response.
This dynamic is part of why researchers in the field are generally cautious about describing any current detection method as a permanent or fully reliable solution. Some theoretical research has gone further, arguing that reliable detection becomes fundamentally difficult as AI-generated and human-written text distributions become more similar. These results describe theoretical limits under particular assumptions rather than proving that all current detectors perform close to random guessing.
What a detector score does and doesn’t prove
It’s worth being direct about the limits here. A detector score is an estimate based on pattern-matching against known examples, not a verified fact about who wrote a piece of text. A high score suggests a passage resembles patterns commonly found in AI-generated writing. It does not, on its own, constitute proof, and treating it as definitive, particularly in contexts with real consequences like academic discipline or employment decisions, runs directly against what the research on detector reliability actually shows.
This doesn’t mean detector scores are useless. In many contexts, they can be a legitimate part of a broader review process, one signal among several that a human reviewer weighs alongside other context, like an author’s known writing style, the plausibility of AI involvement given the circumstances, and any additional supporting evidence, rather than a self-contained verdict.
Frequently asked questions
Can AI detectors be fooled or evaded?
Yes, to varying degrees. Research has shown that paraphrasing, editing, and specialized “humanizing” tools can reduce detection accuracy across multiple types of detectors, though effectiveness varies by detector and by technique.
Is a high AI detection score proof that something was written by AI?
No. A detector score is a probability estimate based on pattern similarity, not direct evidence of authorship. It can be useful context, but independent research generally does not support treating it as standalone proof.
Do all AI detectors use the same method?
No. Different tools rely on different combinations of statistical analysis, trained classifiers, and in some cases watermarking or zero-shot methods, and their accuracy and false-positive rates can vary meaningfully as a result.
Why do some AI detectors flag human-written text as AI-generated? False positives can occur for several reasons, including simple or highly predictable writing styles, non-native English patterns, and formulaic or technical writing that naturally resembles some of the statistical signatures detectors associate with AI text.
Are AI detectors getting more accurate over time?
Detection methods continue to evolve, but so do the techniques used to evade them, and researchers generally describe this as an ongoing dynamic rather than a problem that’s been definitively solved in either direction.
Understanding how detection tools actually work is useful context for anyone navigating AI-assisted writing, whether the goal is evaluating a detector’s output responsibly or simply understanding what these scores can and can’t tell you. If you’re also curious about the tools built specifically to work around these detection methods, what an AI humanizer is and how AI humanizers work covers that side of the same conversation.
